A customer says a café was quiet on a Tuesday morning. Another liked having somewhere to work. A third complains about the noise on Saturday.
What should the business learn from those reviews?
“A quiet place to work” sounds reasonable until the third review disappears from the analysis. “Customers have mixed opinions” preserves the disagreement but loses the useful detail. The interesting question is whether the experience depends on when someone visits, and whether there is enough evidence to say so.
This is an illustrative example, but it captures the problem I work on in Lemtika: extracting useful insights from information a business already has, while keeping each conclusion connected to the material that supports it.
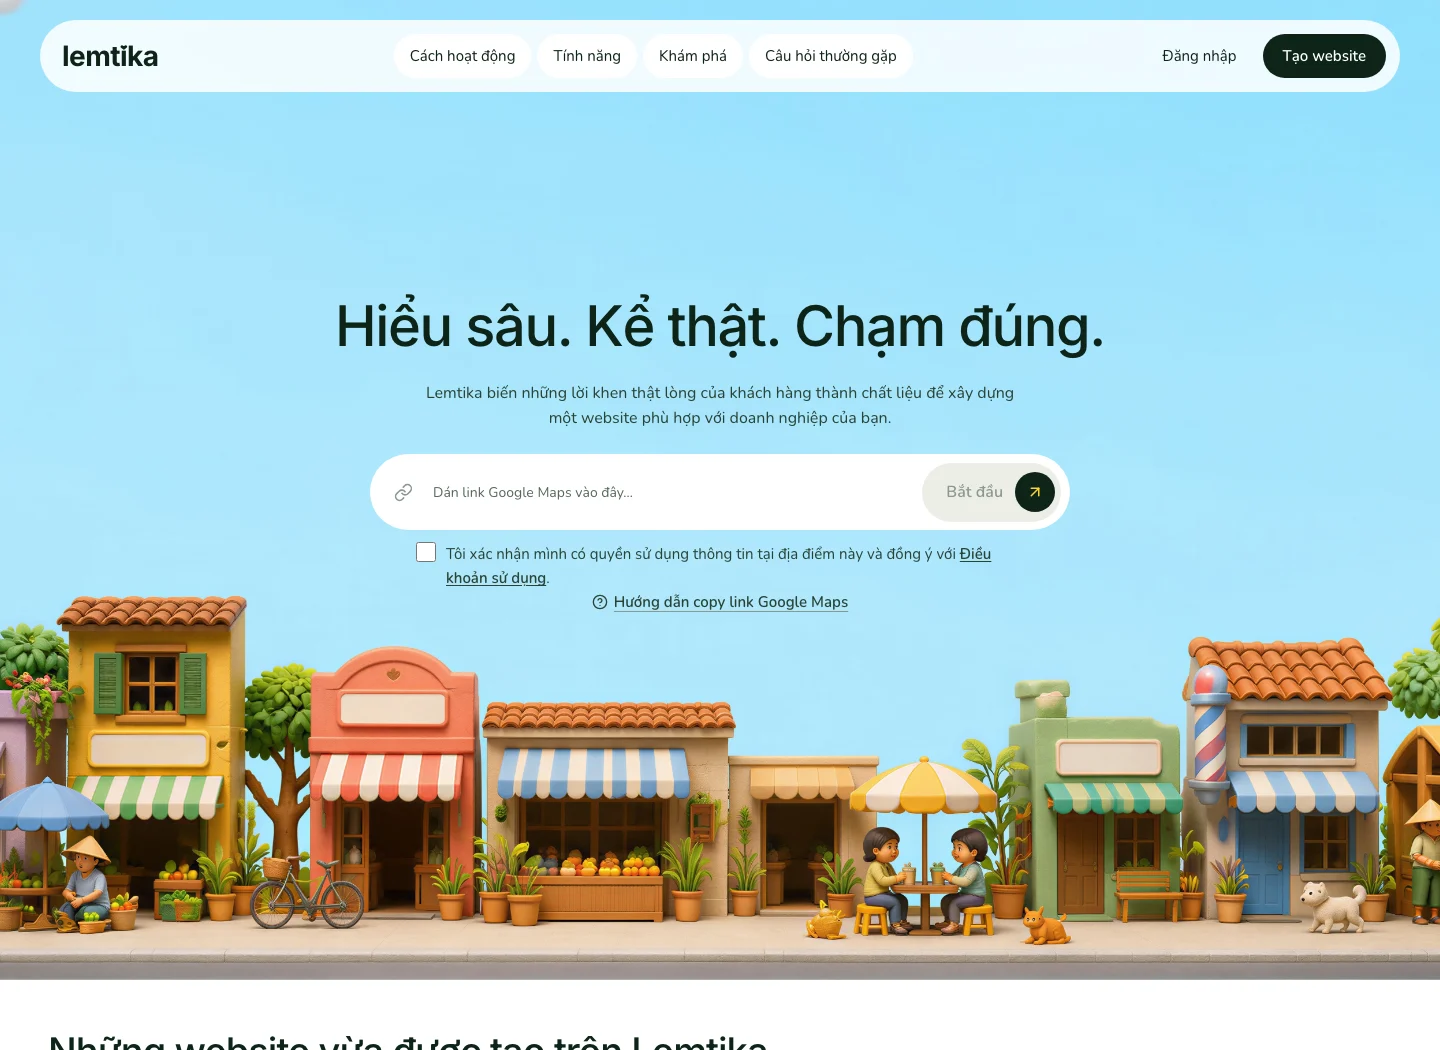
The visible product starts with a Google Maps link and produces a website. Between those two points sits a research system. It reads customer reviews, extracts observations, develops candidate insights, checks their evidence, and decides which findings can support public content. Website generation is one application of that research.
This article follows that path at the architectural level. Model choices, prompts, scoring formulas, and operating thresholds are private implementation details.
Start by separating facts from experiences
A listing gives the system a business identity and structured information such as its category, address, and opening hours. Reviews describe individual experiences. Photos provide material for the presentation.
These sources have different authority. A review saying “we stayed until midnight” does not establish the business's current closing time. A photograph can help illustrate a place without proving what customers consistently value about it.
The import flow resolves the business identity, stores the listing, and checks whether the available material looks sufficient to begin. Research then fetches reviews and retains source records. An early count is only a preliminary check: the system must assess the material that actually survives processing before producing an initial website.
Keeping source records gives later stages something stable to refer to. When a claim looks wrong, I want to inspect the review it came from and the transformation that introduced it.
Extract observations before writing conclusions
A single review can mention several things: helpful staff, a long wait, a particular dish, and limited parking. Reducing it immediately to one summary makes those details harder to check independently.
Lemtika first extracts observations tied to individual reviews and supporting passages. At this level, the task is to identify what someone actually described. A broader claim about the business comes later.
The distinctions matter:
| Layer | Illustrative example | What it establishes |
|---|---|---|
| Source | “Quiet on Tuesday morning; I stayed to work.” | One customer's recorded account |
| Observation | This reviewer described a quiet weekday morning. | A specific experience tied to a passage |
| Candidate insight | Weekday mornings may suit visitors looking for quiet. | A hypothesis to examine across the available evidence |
| Public copy | A sentence selected for the website | A claim that must stay within the supported finding |
Code checks whether extracted quotations occur in their source reviews. Further validation assesses whether an observation is supported by that passage. These checks address different failures: a quotation can be copied correctly while the interpretation attached to it is too broad.
This intermediate layer also makes repair more focused. An extraction problem can be traced to the affected review instead of requiring someone to untangle a polished page of prose.
Give candidate insights room to emerge, then test them
Once the observations exist, the system can look across them for recurring aspects and possible findings. This is where individual experiences begin to become useful business knowledge.
Lemtika separates proposing findings from curating and verifying them. The proposal stage looks for potentially useful signals. Curation consolidates overlapping ideas and examines whether they belong in the result. Verification checks the relationship between a proposed statement and its evidence.
The separation helps because discovery and acceptance have different jobs. During discovery, a subtle but useful detail should have a chance to surface. Before acceptance, that detail must justify the scope of the claim being made.
For the café example, several reviews mentioning laptops might justify investigating a working-friendly atmosphere. They would not, by themselves, establish reliable Wi-Fi, abundant power sockets, or quiet conditions throughout the week. Each additional assertion needs its own support.
An insight therefore needs more than a persuasive sentence. It needs references, an account of its support, and a way to retain disagreement.
Keep contradictory evidence in the picture
A positive quotation can be authentic and still produce a misleading description of a business.
If customers repeatedly mention long waits, choosing one review that praises fast service does not make “consistently quick service” a defensible conclusion. The failure is in how the evidence is combined.
Lemtika carries positive, neutral, and negative evidence into its assessment of an aspect. It has rules for restricting positive claims when the wider evidence runs against them. Verification can then examine a statement alongside its cited material and the broader balance of observations.
That does not turn reviews into objective ground truth. Reviewers are a self-selected group. The material collected for a run is a bounded view of their accounts. Repetition can reveal a pattern in that material without proving its prevalence among all customers or establishing its cause.
In the café example, weekday and weekend differences might be worth investigating. If the source material is too thin to establish that distinction, the system should keep the conclusion narrow or leave it out.
Preserve the research as an output of its own
The research layer produces stored insights with links back to their evidence. It can run separately from building a website.
That boundary is central to how I think about the system. The research answers questions about what the available material supports. A later application decides how those findings should be used.
In Lemtika, the immediate use is presentation: what should a visitor understand about this business? In another implementation, the same architectural pattern could support a feedback report or help a team investigate recurring customer friction. Those uses would need their own source adapters, definitions of a useful insight, and evaluation examples.
A marketing-worthy finding and an operational problem are different outputs. A system designed for public copy should not silently become the policy for deciding which complaints deserve attention.
Carry the evidence into the website
Website generation starts with eligible insights, listing information, and curated media. Photo processing has its own path; its output supports presentation rather than becoming evidence for customer-experience claims.
The generation flow has several responsibilities:
- Propose a narrative and page structure using the available insights and media.
- Validate the proposed references against the actual records.
- Write copy within that supported structure.
- Check the copy and attempt bounded repairs where needed.
- Assemble a structured website document for the presentation layer.
Code owns constraints that can be checked mechanically. Source references must resolve. Numerical claims are checked against evidence. Opening hours have a designated source. A further semantic review looks for problems that reference checks alone cannot catch.
Detected violations that survive repair can lead to content being suppressed or replaced with a conservative fallback. Sections can disappear when there is not enough usable content to support them.
There are two different kinds of sparsity here. An initial import may stop because the usable source material is insufficient. A run that has passed that gate can still yield no eligible narrative insights, in which case generation can fall back to a simpler listing-based page. Having source material does not guarantee that it supports an interesting story.
The backend stores a website document; the presentation layer resolves its references into public content. This keeps research and copy generation separate from rendering the interface.
Make failures inspectable
The pipeline crosses data collection, extraction, synthesis, media processing, generation, and publication. Any of those steps can be interrupted.
Lemtika persists intermediate results and progress so another attempt can determine what remains to be done. Saved checkpoints let the system reuse completed work. Run ownership prevents competing workers from casually advancing the same operation at once.
This is also a quality feature. Stored observations and insights let me inspect where a claim changed meaning. Stage records distinguish a failed check from a completed one. Recovery reduces unnecessary repetition, although a failure around an external request can still leave work that needs to be retried or reconciled.
Checks have limits too. A semantic reviewer is another fallible component, and its unavailability is different from a clean result. I would not describe this architecture as a guarantee that every published sentence is correct. Its value is in constraining generation, exposing evidence, and making specific failures easier to locate and repair.
New evidence should lead to a considered update
A business continues receiving reviews after its website is published. New research may reveal a useful finding or weaken an older one.
For Lemtika's automatic update path, refreshed research produces a candidate document and proposed changes for the owner. It does not directly overwrite the live document. Explicit regeneration is a separate action.
This preserves a distinction between learning something new and deciding to change an existing presentation. The owner may have edited the page, and a new finding may need context before it belongs in public copy.
Applying the pattern beyond Lemtika
The reusable capability is extracting traceable insights from existing material. The output could inform content, a report, or a human decision, depending on the question the system was built to answer.
For a new engagement, I would start with one source collection and one recurring question. We would agree what counts as a useful finding, review examples of supported and unsupported conclusions, and evaluate whether the system preserves important qualifications and disagreements. The first delivery should make it easy to open a finding and inspect why it exists.
I describe that engagement as an Evidence-Based Insight Engine. An AI Content Engine can sit downstream when the business also needs to turn selected findings into usable content.
Lemtika shows how those layers work together: existing business data becomes observations, observations support insights, and selected insights shape a website. The evidence remains available throughout that journey.